
Orchestrator pattern: big models for planning, small models for execution
Introduction
Most agent workloads have two very different jobs inside them: a small amount of planning and judgment, and a large amount of mechanical reading and doing. Web research is the extreme case, and it's the example this notebook uses: verifying twenty facts against their authoritative sources means pulling hundreds of thousands of tokens of web pages through a model, and at frontier rates that reading bill dominates.
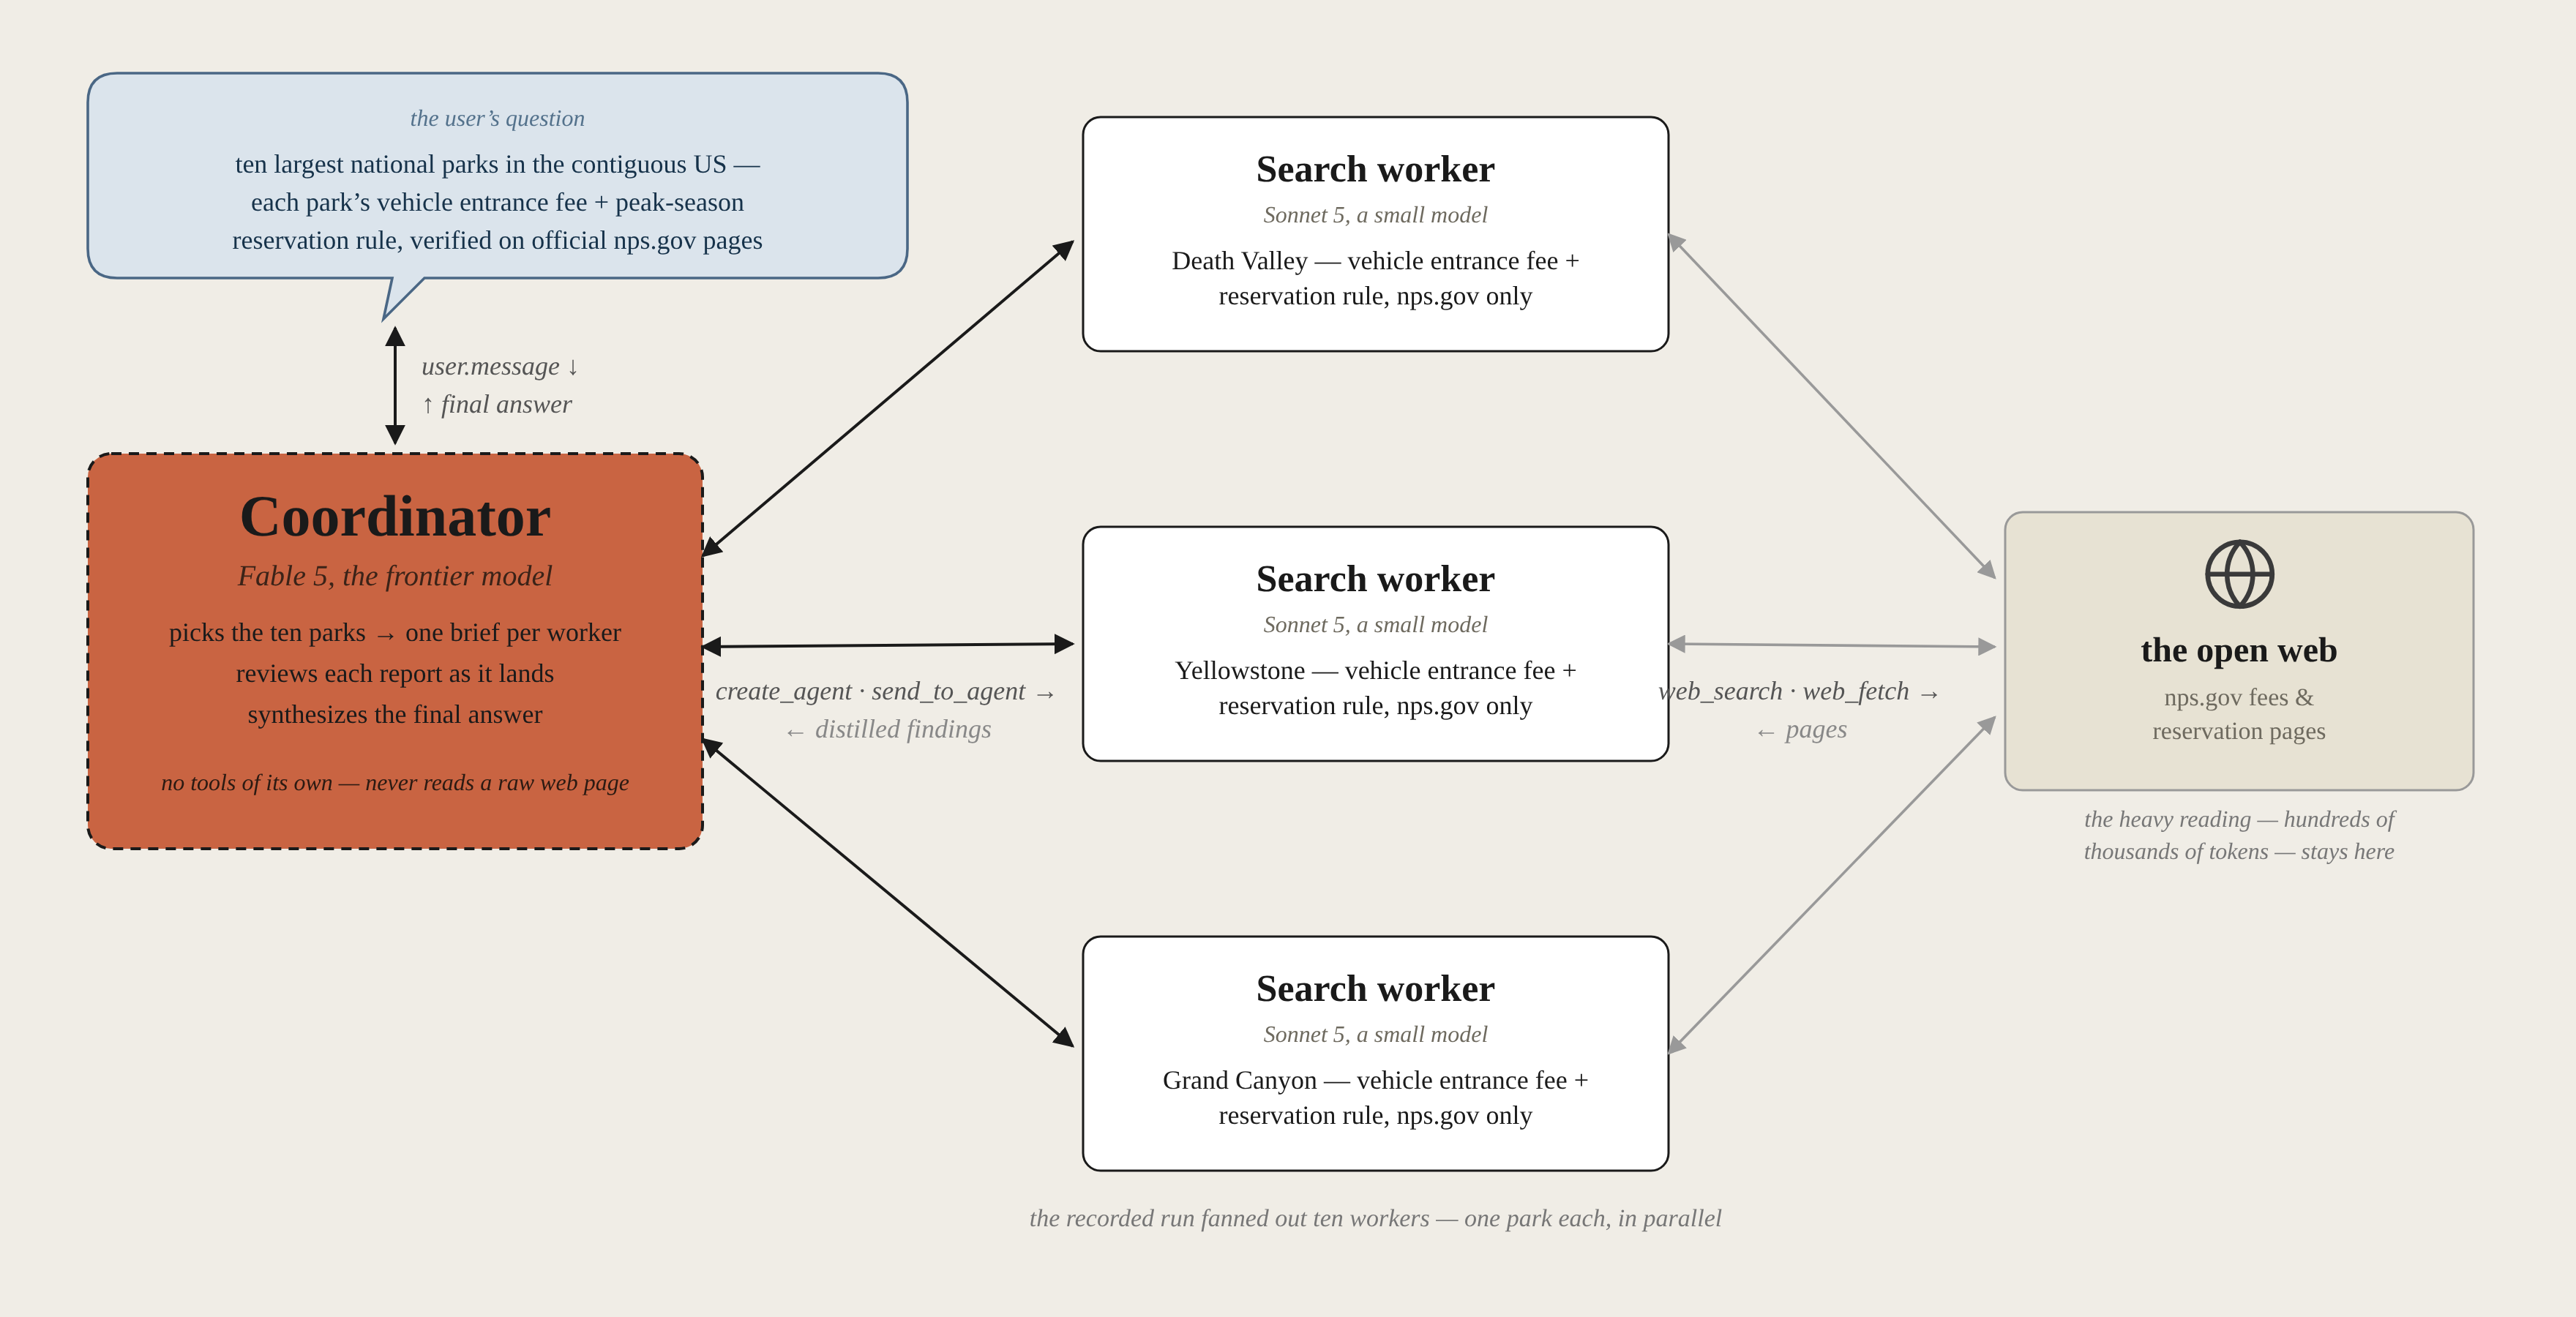
The orchestrator pattern splits the two workloads. A frontier model plans the research and synthesizes the answer, but it never touches a raw web page — cheap workers do all the reading in their own parallel context windows and report back distilled findings. This notebook measures the split honestly: it runs the realistic alternative — one frontier agent with the same tools, held to the same verification standard — on the same question, and compares real bills and real wall-clock. On the authors' runs, made before this notebook moved to the multiagent_20261001 type, both arms read about the same amount, with 84-98% of the team's input tokens billed at the worker rate.
By the end of this cookbook, you'll be able to:
- Configure a two-model team with the
multiagentblock: a frontier orchestrator and cheap search workers - Follow a delegation live through the session event stream (
thread_created,thread_message_sent,thread_message_received) - Run a rigor-matched solo-frontier control and compare real bills
- Meter each thread with the typed per-thread cumulative
usage
The same economics apply to any workload where a cheap model can do the token-heavy leg: document review, log analysis, codebase sweeps.
Prerequisites
Before following this guide, ensure you have:
Required Knowledge:
- Python fundamentals
- Familiarity with the Managed Agents basics — agents, environments, sessions, and the streaming event loop (
CMA_iterate_fix_failing_tests.ipynb(opens in new tab) introduces all of them)
Required Tools:
- Python 3.11 or higher
- Anthropic API key (get one here(opens in new tab)) with access to the Managed Agents beta
If you haven't seen the multiagent block before, the multiagent orchestration documentation(opens in new tab) introduces it. This notebook uses the simplest possible team — one worker type — because the point here is the cost structure, not the team design.
Setup
1. The team: cheap readers, expensive thinker
Two agent definitions make the whole team.
The worker is an ordinary agent: a model, a toolset scoped down to web_search + web_fetch, and a system prompt. The docs call it a subagent, and the orchestrator can delegate to it because you list it in subagents.predefined_agents. Each worker instance researches one focused sub-question in its own session thread, so the giant web pages it reads never enter anyone else's context.
The orchestrator has no tools of its own — only a multiagent block listing the worker. That block is what lets it delegate: the server automatically gives it create_agent, send_to_agent, and list_agents, and workers get send_to_parent the same way. You never define any of those tools.
The block also turns off two things that the multiagent_20261001 type enables by default: inline agents, which the orchestrator would define itself, and workflow runs, in which the server executes a program that the orchestrator writes to run many agents and combine what they return. With either left on, the orchestrator could hand work to agents other than the worker you listed, and the setup would no longer guarantee the split this notebook measures. Setting subagents.inline_agents and workflows to {"type": "disabled"} keeps every delegated task on the worker you listed.
Two things to know about how the orchestrator relates to the workers you list. First, the predefined_agents list is snapshotted when the orchestrator is created or updated — if you change the worker's definition, update or recreate the orchestrator. Second, and less obvious: the orchestrator can't see its workers' system prompts. Its create_agent tool takes an agent name and a task string. Everything the orchestrator believes about how its workers behave comes from its own system prompt, so keep that prompt's description of the workers and the workers' actual prompts in agreement — nothing on the server enforces it. (With several worker types, name them explicitly in the orchestrator's prompt.)
2. Run a research question
Create an environment and a session for the orchestrator, send the question as a user.message, and stream. The session-level stream is the orchestrator's primary thread — a condensed view of the whole run. Worker threads show up in it as delegation traffic: session.thread_created when a worker is spawned, agent.thread_message_sent when the orchestrator hands one a sub-question, and agent.thread_message_received when the findings come back.
The question is a coverage task — twenty facts (10 parks x 2 attributes), each of which must be verified against a specific authoritative source. Coverage questions are where the pattern shines, because the reading is mandatory: nobody gets to answer from memory, so the only question is what rate the reading bills at and whether it happens in parallel. (Discovery questions — find one answer hiding in a big search space, in the style of benchmarks like BrowseComp(opens in new tab) — reward a frontier model's search intuition more, and the gap narrows.)
Fan-out is data-dependent: the orchestrator decides how many workers to spawn, so nothing in the prompt fixes its ceiling. The session below carries a budget, an enforced cap on the whole team's list cost across every thread. The $10 cap is generous enough that a normal run never touches it, but if a bad question ever sent the orchestrator spawning workers without end, the session would pause at the cap instead of running up the bill. The pause mechanics, and raising the cap afterward, are in CMA_cap_session_spend.ipynb(opens in new tab).
The shape to notice: every [delegate ->] line is a small message, and every [report <-] line is a distilled summary. The megabytes of search results and fetched pages that produced those reports never crossed the orchestrator's context. That separation is the entire cost story. To price it fairly, the next section runs the realistic alternative, then we meter both.
3. Run the control: one frontier agent, same verification standard
What would this cost without the pattern? The realistic alternative is a single frontier agent with the same two web tools. One subtlety makes this comparison fair or worthless: the solo agent must be held to the same verification standard. Left to its own judgment, a frontier model is economical — it reads a single source per fact and comes in cheap, but that's a lower-rigor product, not the same work at a different price. So the solo prompt below demands what the team already does: every fact verified from two independent fetches, conflicts re-checked and flagged.
Same question, quiet stream.
4. Meter and price both runs
Cost attribution is built into the API. Every session thread carries a cumulative usage, and both the session and each thread report usage.list_cost: the token cost at public list rates, computed server-side. List the threads, take the primary thread (parent_thread_id is None) as the orchestrator, and the child threads are the workers — the solo session simply has no child threads. The session's own list_cost is the total, so there is no rate table to keep in sync for the headline numbers.
(If you ever need per-request detail instead, it's in each thread's own event feed — the session-level feed only carries the primary thread's span.model_request_end events.)
One number the API can't hand you is a counterfactual: what this exact team workload would have billed at all-frontier rates. That takes a rate table applied to the token counts, so the code keeps the input and output rates from the pricing page(opens in new tab) for that one what-if — 5-minute cache writes bill at 1.25x the input rate, 1-hour writes at 2x, cache reads at 0.1x — and uses list_cost for everything real.
The results described below come from the authors' runs, made before this notebook moved to the multiagent_20261001 type. The two runs did nearly the same reading — that's the point of matching the verification standard. What differs is the rate the reading billed at and the shape of the work: the team's twenty lookups ran as parallel worker threads at the cheap rate, while the solo agent ground through them serially in one frontier-priced context. On the authors' runs, 84-98% of the team's input tokens billed at the worker rate. Token volumes vary run to run, so treat any single printed ratio as one sample; the structure is the stable part.
Four honest caveats, all observed while building this notebook:
- Hold the comparison to matched rigor. A solo frontier agent left to its own judgment reads far less (one source per fact) and comes in cheaper than the team — but that's a different, lower-rigor product. Compare the two arms only with the verification standard held fixed.
- Delegation has a floor cost. Each worker thread pays a fixed setup overhead. Splitting the same work into more, narrower briefs raised our bill instead of lowering it — brief granularity has an optimum.
- The verification standard only covers what you put in it. On one of the authors' runs, both arms verified all twenty facts against nps.gov — and both built their list of parks from model memory, which put Kings Canyon in the #10 slot that actually belongs to Great Smoky Mountains (Kings Canyon is #12 by area). The facts were audited; the question decomposition wasn't. If the premise matters, spend one more delegation making a worker verify it.
- The orchestrator only knows what you tell it. Nothing on the server shows it the workers' prompts (see section 1), so the economics also depend on you describing the workers' behavior accurately in the orchestrator's prompt.
When does the split not pay? On narrow questions there's too little reading to arbitrage. If the orchestrator answers from its own knowledge (no delegation), you paid a frontier round-trip for nothing — watch for runs with no [spawn] lines. And if the task needs frontier judgment on the raw material itself (subtle document analysis rather than fact-finding), a cheap reader may summarize away exactly what mattered.
Recap
In this guide you built the cheapest useful shape of a multi-agent team and measured what it buys:
- Configured a two-model team — a frontier orchestrator with no tools of its own, only a
multiagentblock listing the worker, and a cheap worker scoped to the web tools - Followed the delegation live through
thread_created/thread_message_sent/thread_message_receivedon the session stream - Ran a rigor-matched solo-frontier control and compared real bills and real wall-clock, not estimates
- Metered each thread with the typed cumulative
usageevery session thread carries (session.usageis the whole-team total)
To take this further:
- Add specialist worker types with scoped toolsets —
CMA_coordinate_specialist_team.ipynb(opens in new tab) shows a three-role team and why per-role scoping matters - Put the per-thread metering into your production telemetry: the thread-level usage is how you attribute spend per delegation, not just per session
- Try the same split on your own token-heavy workload — document review and log triage have the same read-heavy, coverage-shaped profile as web research
Reference: multiagent orchestration documentation(opens in new tab).